 CloudFall
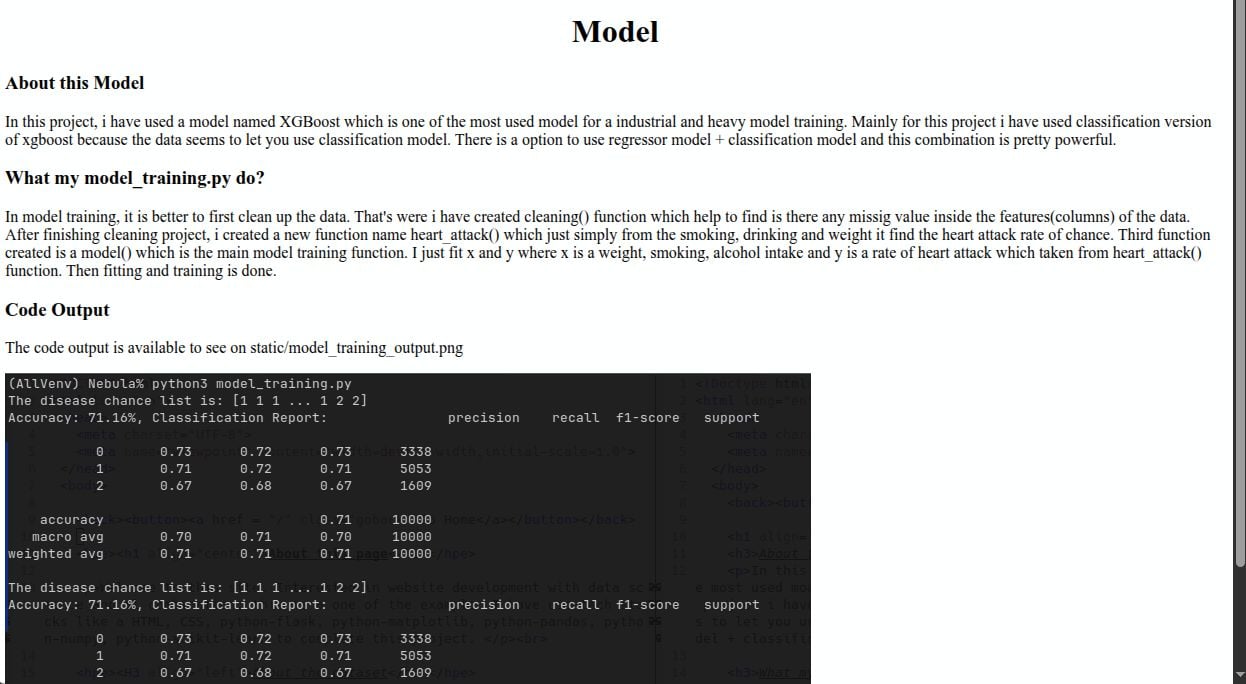
Project goal: It analysis the .csv file then model training and prediction using data. Flask, numpy, pandas, sklearn, xgboost is used in this project.
- 9.2h
- Coding
- Python
- Top language
California-dataset-project
This project is a very simple data science and analysis project uses housing.csv file from a kaggle dataset.
Description Source where the dataset is taken: [kaggle: https://www.kaggle.com/datasets/camnugent/california-housing-prices] Total file: 1 (housing.csv) columns: longitude, latitude, housing_median_age, total_rooms, total_bedrooms, population, households, median_income, median_house_value, ocean_proximity
Tools
- language : python3.
- Libraries : streamlit, numpy, pandas, matplotlib, scikit-learn.
** How to clone **
git clone https://github.com/hemanta-kandel/California-dataset-project.git
cd California-dataset-project
pip install -r requirements.txt
python main.py
The app is live on: [https://california-dataset-project.streamlit.app/]